GPT-6 Astra After Launch: Worth the Hype?
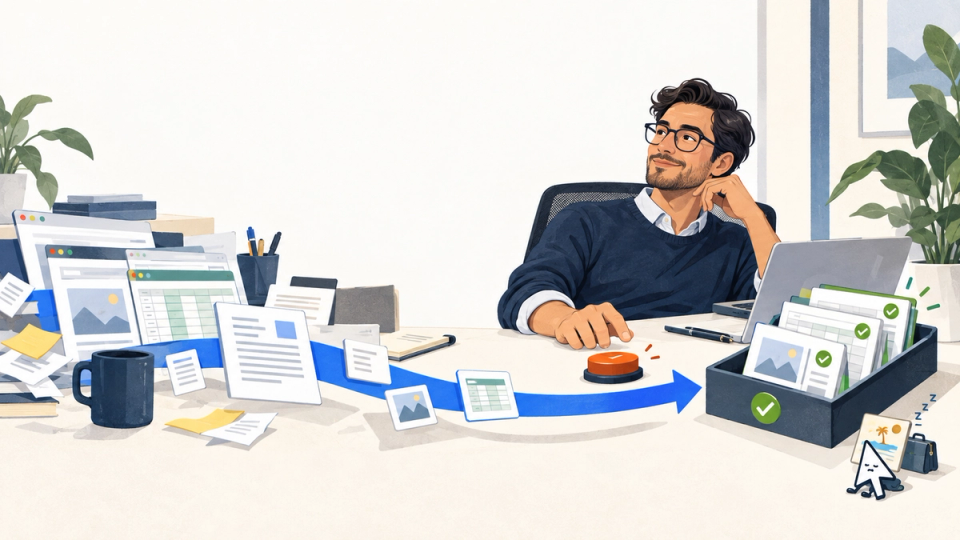
Eleven days after launch, GPT-6 Astra looks worth the hype for one narrow class of work: bounded, multi-step tasks where a stronger agent reduces supervision. It is not a reason to replace lower-cost models for routine work, or to hand an agent an open-ended business process.
OpenAI’s published computer-use and coding results are a real step up, and early vendor-published deployment reports from Perplexity and Cognition are encouraging. But benchmark charts and customer stories are not independent reliability data. The practical standard is simpler: give Astra one reviewable artifact, the least access it needs, and an approval gate for irreversible actions. If it consistently produces accepted work with less review than your current path, it earns its premium.
The article below explains the use cases that meet that bar, the ones that do not, and a three-part test for deciding where to delegate.
OpenAI released GPT-6 Astra on September 3, 2026, positioning it as its flagship model for computer use, browsing, professional work, and coding. Its best claim is not that it can click more buttons. It is that it may let people hand off longer stretches of computer work and spend their time reviewing a result instead of operating every step.
That is the same threshold Whisper crossed for voice in 2022. Whisper did not make speech recognition new. It made transcription robust enough across accents, noise, and languages that it could become part of everyday work. Astra is trying to cross that threshold for the computer itself. The difference is that a transcription error is usually editable. A computer-use error can change a record, send a message, or expose data. So the useful question is not “Can Astra operate a computer?” It is “Which work can now become a safe, reviewable handoff?”
What happened
OpenAI says GPT-6 Astra is available as gpt-6-astra through the API, Azure, and AWS Bedrock, and is rolling out across ChatGPT Plus, Pro, Business, and Enterprise. The company lists a 1.05 million-token context window, 128,000 maximum output tokens, and support for functions, web search, file search, and computer use. Standard API pricing is $10 per million input tokens and $50 per million output tokens. OpenAI’s model catalog describes Astra as the default flagship for hard end-to-end reasoning and coding work.
The computer-use numbers are material, but they are not a blanket guarantee. On OpenAI’s OSWorld 2.0 evaluation, Astra scored 72.6%, versus 65.7% for GPT-5.6 Sol. The company says that run took about 40 minutes per task, compared with about 75 minutes for Sol, in its latency simulations. On its AutomationBench professional-work benchmark, Astra scored 41.4%, against Sol’s 18.1%.
Those results help explain the product shift. A model that sees the screen, keeps enough task context, uses tools, and finishes a task faster changes the value of an agent from “show me how” to “prepare this for my approval.” But OpenAI has not published a universal success rate for real customer workflows. Benchmarks are evidence, not permission to skip review.
Greg Kamradt of the ARC Prize Foundation said Astra surpassed its human action-efficiency baseline on 96% of ARC-AGI-3 levels. That is a strong sign of navigation and adaptation, not proof that the model should be left alone with a payroll system.
Does Astra make the computer autonomous?
Not in the only sense that matters. Astra makes multi-step delegation more plausible, but consequential computer work still needs clear scope, confirmation points, and a human owner. The right unit of adoption is a finished artifact you can inspect, such as a populated draft, a reconciled table, or a research brief, not an open-ended instruction to “take care of it.”
OpenAI’s own deployment details point in that direction. Its monitoring can pause or stop tasks that appear unauthorized, and users may be asked to review an action before continuing. The company also says Astra met its Critical cybersecurity threshold, which is precisely why the model’s ability to act must be paired with stronger safeguards. Better computer use raises both the productivity ceiling and the cost of sloppy permission design.
This is where AI assistance and AI decision-making stop being separate ideas. Astra can gather evidence, update a draft, test a site, and surface a recommendation. It has not earned the authority to decide who gets paid, what gets signed, or what sensitive data leaves a system. The model can carry the work forward. A person still owns the decision.
Why is this more like Whisper than a new chatbot?
Whisper became useful because it removed a repeated conversion cost. Speaking became editable text without a special setup ritual. Astra’s potential is similar: it can reduce the repeated conversion of human intent into browser clicks, form fields, copied context, and hand-built documents.
The comparison has a hard limit. Whisper’s output is a draft. Computer use has side effects. That makes the productive interface a review loop, not a black box. Ask Astra to collect sources and produce a comparison. Review the citations. Ask it to prepare a CRM update. Review changed fields. Ask it to test a website. Review the report and the diff. Keep purchases, sends, publishing, access changes, and other irreversible outcomes behind an explicit approval.
This is also why the case for Grok 4.6 as a cheap agent rather than merely a smart model is incomplete by itself. Agent economics are not only the cost per token or the time per task. They include review time, retries, permission scope, and the cost of fixing a bad action. Astra’s price is 2.5 times GPT-5.6 Sol on both standard input and output rates. It earns that premium only when the result is accepted with materially less human intervention.
Who should change their computer workflow first?
Individual operators should start with read-heavy, reversible tasks: turn a set of web pages into a cited brief, compare options against a fixed rubric, or prepare a travel, purchasing, or job-search shortlist. The final choice stays with the person. The gain comes from avoiding tab choreography.
Teams should start where there is already a review step. Sales operations can have Astra prepare CRM changes for approval. Product teams can have it run a defined QA script and attach evidence. Analysts can have it assemble a first-pass spreadsheet or presentation from approved sources. Use a fixed input set and a clear definition of done. If a task cannot be reviewed in minutes, it is not a first deployment.
Builders should stop treating the chat box as the whole interface. Astra has to know what it can see, what tools it may use, which actions require confirmation, and what evidence it must return. The most useful agent product will make those boundaries legible before it starts work. Magic Pointer’s critique of the agentic browser remains relevant here: people want help at the point of work, without becoming spectators to a mysterious process.
A three-part Astra test before you automate anything
- Choose one artifact. Define the output before the task begins: a brief, a list of changed CRM fields, a test report, or a draft document.
- Set the boundary. Grant the smallest useful access. State which sites, files, fields, and actions are in scope, and which are off limits.
- Measure accepted work. Track whether the output was accepted, how long review took, how many corrections were needed, and whether the agent stayed inside scope. Do not measure polished prose or benchmark claims alone.
This test turns a model launch into an operating decision. If Astra reliably produces an accepted artifact while you do other work, it has changed the workflow. If you spend the whole task rescuing it, the old interface is still faster.
What to watch next
Watch the gap between a computer-use benchmark and a production workflow. OpenAI’s 72.6% OSWorld 2.0 score is impressive, but it still leaves failures. The decisive improvement will be a shorter, clearer review loop: fewer unexpected actions, better source trails, more accurate scope boundaries, and cleaner recovery when an interface changes.
Also watch cost. At $10 per million input tokens and $50 per million output tokens, Astra should be reserved for tasks where higher judgment removes a meaningful amount of review or rework. It is not the economical default for every summary, classification job, or simple edit. Kimi vs Claude vs GPT vs Gemini: Pick by Failure Mode is still more useful than choosing by the newest headline.
The bottom line
GPT-6 Astra does not change how people use computers because it can impersonate a user for longer. It changes the possibility space because it combines computer use with stronger task continuity, evidence gathering, and professional artifact creation. That can turn a batch of browser work into a reviewable output.
Whisper taught us that a capability becomes productive when its errors are cheap enough to correct. Astra will earn the same status only when people can delegate real work, inspect the result quickly, and retain control over anything consequential. Start there: one bounded workflow, one reviewable artifact, one explicit approval boundary.
Frequently asked questions
Is GPT-6 Astra available in regular ChatGPT?
Availability depends on plan and product surface. OpenAI says GPT-6 Astra is rolling out to Plus, Pro, Business, and Enterprise users, while GPT-6 Pro is the Chat offering for eligible Pro, Business, and Enterprise plans. Access can differ between Chat, Work, and Codex.
What does GPT-6 Astra cost?
The standard API rate is $10 per million input tokens and $50 per million output tokens. Fast mode is priced higher. Actual spend also depends on context size, tool use, and the mix of input and output tokens.
Is Astra safe to use for sensitive browser tasks?
It should be used with boundaries. OpenAI says it applies monitoring and may pause risky work, but its safety controls do not remove the need for human review, least-privilege access, and explicit approval for consequential actions.