Claude Opus 5 Is Anthropic's Cost-Performance Move
Anthropic released Claude Opus 5 on July 24, 2026, positioning it as a model that comes close to Claude Fable 5's frontier intelligence at half the price. It is available across Anthropic's platforms at the same $5 per million input tokens and $25 per million output tokens as Opus 4.8. Read Anthropic's official Claude Opus 5 announcement for the launch details and benchmark methodology notes.
The important story is not simply that Anthropic has a stronger flagship. Opus 5 is designed to make long-running agent work more economical: better verification, more useful effort controls, and stronger results per task at the same sticker price. That makes it a migration candidate for developers running coding, research, and knowledge-work agents, but not a reason to replace every model in a stack today.
What happened
Anthropic says Opus 5 is available today on Claude, Claude Code, Claude Cowork, and the Claude API under the model name claude-opus-5. It is the default model on Claude Max and the strongest model available on Claude Pro. Fast mode runs at about 2.5 times the default speed and costs twice the base price on the Claude Platform.
The release keeps the Opus 4.8 price: $5 per million input tokens and $25 per million output tokens. Anthropic's framing is therefore performance per dollar, not a cheaper list price. On CursorBench 3.2 at maximum effort, the company says Opus 5 comes within 0.5% of Fable 5's peak score at half the cost per task. On Frontier-Bench v0.1, Anthropic says Opus 5 more than doubles Opus 4.8's performance at a lower cost per task.
The same pattern appears in Anthropic's other reported evaluations. Opus 5 scores three times higher than the next-best model on ARC-AGI 3, achieves about 1.5 times the pass rate of the next-best model on Zapier AutomationBench at the same cost per task, and beats Fable 5's best OSWorld 2.0 result at just over one-third of the cost. These are Anthropic-reported results, so they are useful launch evidence, not a substitute for testing your own workloads.
The model also improves on scientific and visual work. Anthropic reports a 10.2 percentage-point gain over Opus 4.8 on an internal organic-chemistry benchmark and a 7.7-point gain on a protein-variation task. Its release examples emphasize interactive artifacts, code that checks its own output, and agents that keep iterating after the first plausible answer.
For context, our earlier coverage of Claude Opus 4.8 and Claude Code as a platform update focused on the shift from model calls to agent infrastructure. Opus 5 continues that shift, but makes the unit of competition clearer: the completed task, not the isolated response.
Is Claude Opus 5 actually cheaper than Fable 5?
Yes, for the published API prices, but the comparison needs care. Opus 5 costs $5 per million input tokens and $25 per million output tokens, while Anthropic describes it as near Fable-level intelligence at half the price. That “half” claim refers to cost per task in the cited evaluations, not necessarily a universal halving of every token bill.
The distinction matters because agents spend money through retries, tool calls, long reasoning traces, and human cleanup. A model that finishes a coding task in one verified pass can be cheaper than a cheaper model that loops. Opus 5's effort setting gives teams a way to trade capability for token use instead of forcing every request through maximum reasoning.
The practical test is simple: record total tokens, tool calls, elapsed time, retries, and reviewer corrections for a representative task set. Compare completed-workflow cost against Opus 4.8 and the model you use today. Do not infer savings from the list price alone.
What changed from Opus 4.8?
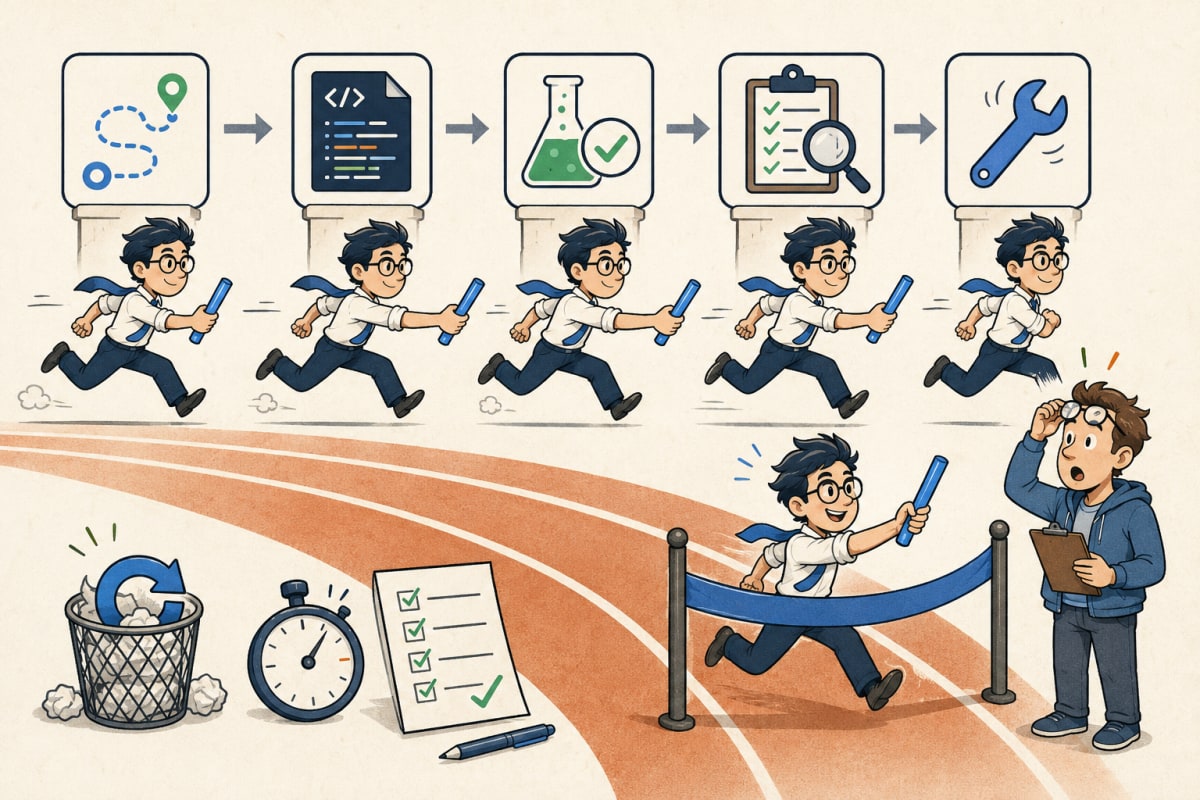
Opus 5 is a meaningful step up in agentic reliability rather than a completely different product category. Anthropic emphasizes that it verifies its work, adapts its strategy, and keeps iterating until it reaches a stronger result. On a machine-part task, it reportedly wrote its own computer-vision pipeline from raw pixels before rebuilding the part as a 3D FreeCAD model.
That behavior is more important than a single leaderboard position. In long-horizon work, the common failure is not inability to produce a first answer. It is stopping after a plausible but incomplete answer. Anthropic's examples point to a model that spends more effort on validation, finds missing edge cases, and builds a test harness when no live validation target exists.
There is also an efficiency signal. A financial-modeling customer quoted in Anthropic's launch material reported 9 percentage points higher accuracy, one-third fewer turns and tool calls, and 60% less time across difficult tasks. A legal-work customer reported similar quality at lower reasoning levels while using 26% fewer tokens on average than Opus 4.8 at maximum reasoning. These are customer reports, not independent audits, but they identify the behavior to measure.
This is why the release belongs beside Claude Fable 5's prompting guide rather than in a simple model-ranking chart. The useful question is how much autonomy your workflow can safely absorb, and how much verification it needs before handoff.
Who should switch first?
Solo developers and small teams should test Opus 5 on tasks where a missed edge case costs more than extra inference. Good candidates include difficult debugging, codebase migrations, browser-tested interface work, and research that needs a cited, structured output. Start with a fixed evaluation set and compare the number of human interventions, not just the final answer quality.
Engineering teams with agents already running in production have a stronger reason to trial it. The reported gains in tool use, self-checking, and long-running work could reduce the supervision burden. But teams should pin the model ID, capture traces, and define rollback criteria. Model providers can change routing and safety behavior, and a stronger agent can also make larger changes before a human notices. Our analysis of Fable 5's code-side effects is a useful reminder that better code generation does not automatically preserve the contract around a codebase.
Enterprise buyers should wait for evidence on their own documents, permissions, and governance constraints. Opus 5 is available through Anthropic's platform and major cloud routes, but the release's public material does not provide a complete independent picture of latency, enterprise pricing, regional availability, or performance under every data-retention configuration. AWS says Opus 5 is available through Amazon Bedrock and Claude Platform on AWS with zero data retention enabled by default on Bedrock. That is useful for governed deployments, but it still needs an architecture review.
What are the safety and availability caveats?
Opus 5 is generally available, but it is not Anthropic's strongest model for every risky capability. Anthropic says it remains behind Mythos 5 in biology research and offensive cybersecurity. It also says Opus 5 can identify vulnerabilities at a level close to Mythos 5 while remaining substantially behind it at developing exploits.
The safety design is intentionally narrower than Fable 5's on some cyber tasks. Anthropic says flagged requests in Claude.ai, Claude Code, and Claude Cowork fall back to Opus 4.8 by default, while API users can enable automatic fallbacks. That means developers should test not only successful outputs but also fallback behavior, refusal paths, and the model identity returned to downstream systems.
Anthropic reports a 2.3 score for overall misaligned behavior on its automated behavioral audit, the lowest among the recent models it lists. That is a useful signal, but it is an internal evaluation. Treat it as evidence about Anthropic's testing, not a universal safety guarantee.
What to watch next
The first 30 days should answer three questions. Does Opus 5 reduce completed-task cost outside Anthropic's launch benchmarks? Does its stronger self-verification reduce human review, or does it simply produce longer traces? And do fallback and classifier behavior remain predictable in real developer workflows?
Watch for independent benchmark runs, model-specific API documentation, and production reports from coding tools. Also watch whether Anthropic keeps Opus 5 as the default for high-end paid plans or routes more work toward Sonnet 5 as that model closes the capability gap. The market is moving toward portfolios of models with different intelligence, cost, and speed profiles.
The bottom line
Claude Opus 5 looks less like a dramatic price cut than a cost-per-completed-task upgrade. Anthropic is offering near-Fable performance at Opus pricing, stronger agentic verification, and an effort dial that lets teams spend compute where it matters.
Use it first on work where failure is expensive and the output can be checked: code, documents, browser interactions, and structured research. Keep Opus 4.8 or a cheaper model in the loop until your own traces show that Opus 5 finishes more work with fewer interventions. The decision rule is straightforward: migrate when it lowers the cost of a verified result, not when it wins a launch chart.
When was Claude Opus 5 released?
Anthropic announced Claude Opus 5 on July 24, 2026, and says it is available immediately across its platforms and API. The API model name is claude-opus-5.
How much does Claude Opus 5 cost?
The published base price is $5 per million input tokens and $25 per million output tokens, the same as Claude Opus 4.8. Fast mode costs twice the base price on the Claude Platform.
Is Opus 5 better than Fable 5?
Anthropic positions Opus 5 as close to Fable 5 on many coding and knowledge-work tasks, while Fable remains the more capable model overall in Anthropic's lineup. Opus 5's advantage is the reported cost-performance ratio.
Should developers replace Opus 4.8 immediately?
Not without testing. Opus 5 is a strong candidate for a controlled migration, especially for long-running agentic work, but teams should compare completed-task cost, tool calls, latency, retries, and human corrections on their own workloads.